The screenshotrun-mcp server gives AI agents four tools: capture screenshots, analyze page structure, extract metadata, and check usage quota. Install it once, set your API key, and Claude, Cursor, or Windsurf can screenshot any URL, pull structured JSON from any page's DOM, and read OG tags — all through natural language requests.
MCP (Model Context Protocol) is the standard for connecting AI models to external tools. An MCP server exposes functions that the agent discovers and invokes on its own. No wrapper code, no SDK imports, no prompt engineering to teach the API schema. The agent sees the tool list, picks the right one, fills in the parameters, and handles the response.
What changed in v1.2: the agent can read pages, not just see them
Before v1.2, this MCP server had two tools: take_screenshot and check_usage. The agent could capture what a page looks like, but it couldn't tell you what was on it without parsing the image. That's slow and unreliable — vision models hallucinate button text, miss form fields, and can't return pixel coordinates.
Version 1.2 adds analyze_page and extract_content. Now the agent gets structured data: every heading with its level, every button and link with its text and position, every form with its field count, every image with its alt text. Each element comes with a bounding rectangle — four numbers: x, y, width, height in pixels. The agent knows not just what is on the page but where it sits.
Four tools the agent gets
take_screenshot captures a screenshot of any URL, raw HTML, or Markdown. It passes through all 50+ API parameters: viewport dimensions from 320 to 3840, PNG/JPEG/WebP/PDF output, full-page capture, dark mode, mobile and tablet emulation, ad blocking, CSS/JS injection, element targeting, geolocation, stealth mode, PDF generation, and scroll video recording. The agent picks the right parameters based on your plain-language request.
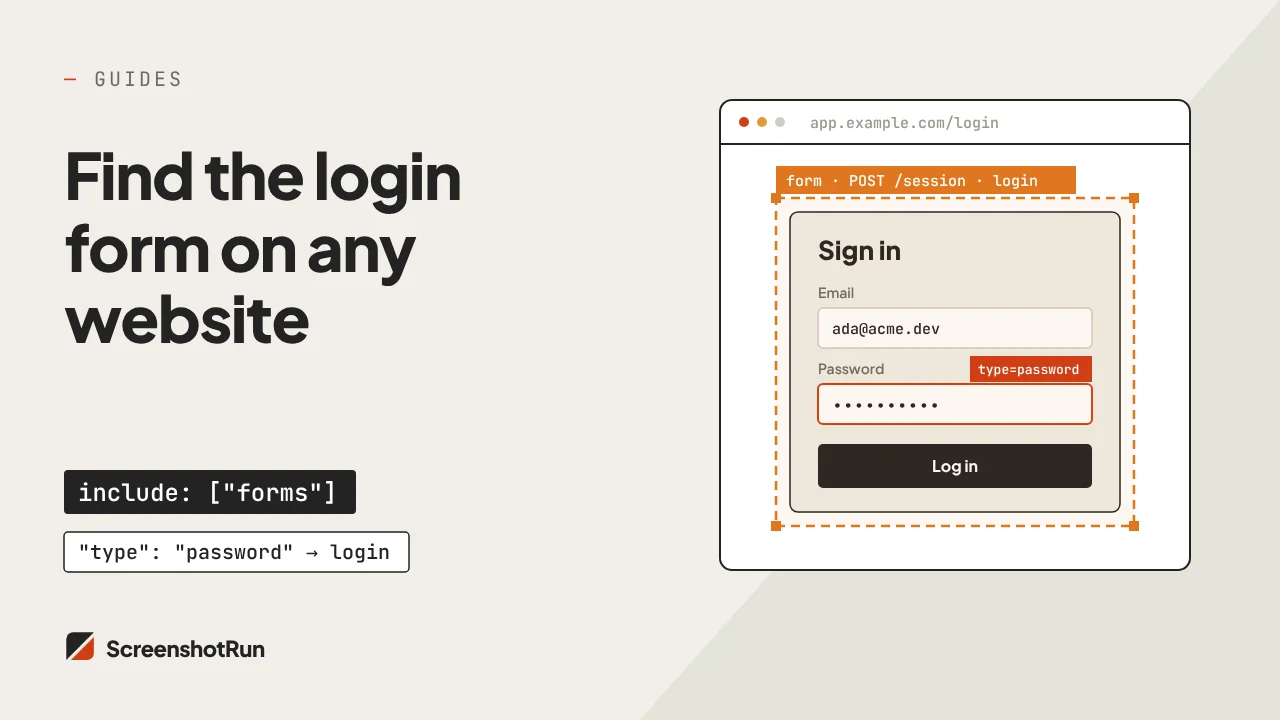
analyze_page scans a rendered page and returns structured JSON with six element categories: headings, interactive elements (buttons, links, inputs), forms, images, text blocks, and navigation sections. Every element carries a rect array with pixel coordinates. Use the include parameter to request only the categories you need. The scope parameter restricts analysis to a specific CSS selector. See the full analyze endpoint documentation.
extract_content pulls page metadata without rendering a screenshot: title, meta description, Open Graph tags (og:title, og:description, og:image, og:type, og:url, og:site_name), Twitter Card tags, favicon URL, and HTTP status code. One API call instead of scraping the HTML yourself.
check_usage returns your current quota: screenshots used, screenshots remaining, usage percentage, and billing period dates. When the agent runs batch operations, it checks before starting and stops before hitting the limit.
Two minutes to install
It's published as screenshotrun-mcp on npm. No global install. npx pulls and runs it on demand.
For Claude Desktop, add this to your MCP config:
{
  "mcpServers": {
    "screenshotrun": {
      "command": "npx",
      "args": ["-y", "screenshotrun-mcp"],
      "env": {
        "SCREENSHOTRUN_API_KEY": "sr_live_your_key_here"
      }
    }
  }
}
Restart Claude Desktop. Four tools appear immediately.
For Claude Code:
claude mcp add screenshotrun npx -y screenshotrun-mcp -e SCREENSHOTRUN_API_KEY=sr_live_your_key_hereCursor and Windsurf use the same JSON format. Drop it into .cursor/mcp.json or the equivalent config file.
What the agent can do with analyze_page
Screenshots answer "what does this page look like?" The analyze tool answers "what's on this page, and where?" That distinction matters for any task where the agent needs to act on page content rather than just display it.
Ask Claude to "check if our pricing page still has an H1 and at least one CTA button above the fold" and it calls analyze_page with include: ["headings", "interactive"]. The response tells it the H1 text, its position, every button on the page, and their coordinates. The agent compares the button's y-coordinate against 800 pixels (a rough fold line) and reports back. No vision model involved, no image parsing, no hallucinated text.
Other workflows that open up:
- Audit heading structure across 20 pages — the agent requests
include: ["headings"]for each URL and checks for missing H1s, skipped levels, or duplicate headings - Map all forms on a competitor's site —
include: ["forms", "interactive"]returns form actions, field counts, and every input element - Verify a deploy didn't break the navigation — compare nav link counts before and after
- Find all images missing alt text — the
imagescategory returns each image's alt attribute (or lack of it) - Detect whether a CTA button moved below the fold after a CSS change — the
rectarray shows exact pixel position
Screenshot + analyze in one MCP server: why it matters
Most MCP servers for web interaction do one thing. Firecrawl returns markdown and crawl data — useful for feeding documents to RAG pipelines, but it strips element types and spatial data. You get the text of a page, not its structure. Puppeteer MCP and Playwright MCP give full browser control but require a local Chromium install, consume hundreds of megabytes of RAM per instance, and expose dozens of low-level methods the agent has to chain correctly. Playwright MCP alone burns 15,000 tokens just on tool definitions before the agent does anything — and a single test run can cost 114,000 tokens of context.
Having screenshot capture and structural analysis in one server means the agent can verify both visually and structurally in a single conversation. "Take a screenshot of our homepage and also analyze its heading structure" produces a PNG and a JSON response from two tool calls to the same server. No second MCP to configure, no context switching between different tool vocabularies.
QA workflows benefit most from this combination. The analyze call checks that the expected elements exist and sit in the right positions. If something looks off, the screenshot provides visual evidence to attach to a bug report or Slack alert. One MCP server handles both the automated check and the human-readable proof.
Where MCP beats a raw HTTP call
You could skip MCP and have the agent build HTTP requests to the screenshot API directly. That works, but there are practical differences worth knowing.
Tool discovery is automatic. The agent sees what parameters exist without you pasting API docs into the prompt. Auth lives in the config file — the API key never appears in the conversation, never leaks into generated code, never gets hardcoded into a script the agent writes. And parameter validation happens at the MCP client layer. A wrong type in a raw HTTP request returns a 400 that the agent has to parse and retry. An MCP call with invalid input gets caught before it reaches the server.
If you're already using MCP with other tools (database queries, file operations, Slack messaging), adding screenshot and analyze capabilities is one more entry in the same config file. The agent treats it like any other tool in its toolkit.
Workflows that work once the agent can both see and read pages
Post-deploy verification: the agent analyzes the staging URL for expected headings and buttons, then captures a full-page screenshot as visual evidence. If the heading count dropped or a CTA vanished, it flags the issue with both the JSON diff and the screenshot attached. Covered in depth in page content verification.
Competitor monitoring: capture screenshots of competitor homepages weekly for visual change tracking. Run analyze_page on each to extract heading text, CTA copy, navigation structure, and form configurations. The agent diffs the structured data between weeks and compiles a report of what changed. With geolocation, it checks both US and EU versions.
SEO auditing at scale: the agent requests include: ["headings", "images", "navigation"] across your entire sitemap. It checks for missing H1s, images without alt text, heading hierarchy violations, and inconsistent navigation. The structured JSON makes this a data problem, not a visual inspection problem.
OG image verification: after publishing a blog post, the agent extracts metadata via extract_content to confirm the og:title, og:description, and og:image are set correctly. Then it captures the page at 1200x630 to verify the social card renders as intended. Two tool calls, complete verification.
Accessibility spot-checks: the agent pulls form data to verify that input fields have labels, buttons have accessible names, and interactive elements are reachable by keyboard. The bounding rectangle data reveals whether elements overlap or sit too close together.
Limitations to know about
Public URLs only. Localhost, VPN-gated dashboards, pages behind authentication — none of these work without exposing them publicly first. That's a constraint of any cloud-based screenshot API, not specific to MCP.
Speed: a screenshot or analysis takes 2–8 seconds depending on page complexity. In conversation, barely noticeable. In a batch of 200 URLs, the agent processes them one at a time — no parallel capture from MCP. For high-volume batch work, direct API calls with concurrent Python requests will be faster.
Multi-step interactions are limited. The click_selector parameter handles a single click (dismissing a modal, expanding a dropdown), but login flows, multi-page wizards, or infinite scroll sessions need a full Playwright script. For those, the API is the wrong tool.
take_screenshot parameter reference
Every parameter from the REST API is available as a tool argument. The agent picks the right ones based on your natural language request.
| Parameter | Type | Default | Notes |
|---|---|---|---|
url | string | — | Any public URL |
html | string | — | Raw HTML to render (max 500KB) |
markdown | string | — | Markdown to render (max 500KB) |
format | string | png | png, jpeg, webp, pdf |
width | integer | 1280 | 320–3840 |
height | integer | 800 | 200–2160 |
full_page | boolean | false | Entire scrollable page |
quality | integer | 80 | 1–100 (jpeg/webp) |
device | string | desktop | desktop, mobile, tablet |
dark_mode | boolean | false | prefers-color-scheme: dark |
retina | boolean | false | 2x device pixel ratio |
block_ads | boolean | false | Removes ad scripts/iframes |
block_cookies | boolean | true | Hides consent banners |
stealth | boolean | false | Avoids bot detection |
delay | integer | 0 | 0–10s wait before capture |
css | string | — | Custom CSS (max 10KB) |
js | string | — | Custom JavaScript (max 10KB) |
selector | string | — | Capture a specific element |
hide_selectors | string | — | CSS selectors to hide |
click_selector | string | — | Click before capture |
geolocation | object | — | {latitude, longitude} |
analyze_page parameter reference
| Parameter | Type | Default | Notes |
|---|---|---|---|
url | string | — | Required. Any public URL. |
include | string[] | all | headings, interactive, forms, images, text, navigation |
visible_only | boolean | true | Only visible elements |
scope | string | — | CSS selector to limit scan area |
with_screenshot | boolean | false | Grab a screenshot alongside JSON |
width | integer | 1280 | Viewport width |
height | integer | 800 | Viewport height |
device | string | — | desktop, mobile, tablet |
dark_mode | boolean | false | Dark mode emulation |
block_ads | boolean | false | Block advertisements |
block_cookies | boolean | true | Block consent banners |
stealth | boolean | false | Stealth mode |
geolocation | object | — | {latitude, longitude} |
check_usage takes no parameters. extract_content takes a single url parameter and returns title, description, OG tags, Twitter Card tags, favicon URL, and HTTP status.
Full parameter specs in the MCP documentation and analyze API reference.
FAQ#
Four tools. take_screenshot captures any URL, raw HTML, or Markdown as PNG, JPEG, WebP, or PDF with 50+ parameters (viewport, device emulation, dark mode, full-page, ad blocking, geolocation, stealth mode, and more). analyze_page returns structured JSON with headings, buttons, links, forms, images, text blocks, and navigation — each with pixel coordinates. extract_content pulls page metadata (title, OG tags, Twitter Card, favicon, HTTP status) without rendering a screenshot. check_usage returns your current quota and billing period.
Any MCP-compatible client works. Claude Desktop, Claude Code, Cursor, and Windsurf are the most common. The config format is the same across all of them — a JSON block pointing to npx screenshotrun-mcp with your API key as an environment variable. Claude Code also accepts a single terminal command.
Three differences. First, no local browser install — ScreenshotRun runs Chromium in the cloud, so there is no Chromium binary to manage or update. Second, token efficiency — Playwright MCP loads 15,000 tokens of tool definitions and a single test run can cost 114,000 tokens. ScreenshotRun exposes 4 focused tools with minimal schemas. Third, structured page analysis — analyze_page returns categorized elements with pixel coordinates, which Playwright does not offer natively.
Yes. The analyze_page tool scans a rendered page in Chromium and returns structured JSON with six categories: headings (level and text), interactive elements (buttons, links, inputs with tag, text, href), forms (action, method, field count), images (alt, src), text blocks, and navigation sections. Every element includes a rect array with pixel coordinates from getBoundingClientRect(). You can request specific categories with the include parameter and scope the scan to a CSS selector.
Yes. Every request runs in a real Chromium browser that executes JavaScript before capturing or analyzing. React, Vue, Angular, Next.js, and Svelte applications render fully. Enable stealth mode for sites that detect and block headless browsers.
Yes. The free plan includes 100 screenshots per month and 20 page analysis calls per month. No credit card required to start. Paid plans scale to thousands of captures per day.